
Contents
A Complete Guide to DataOps

Category: DataOps | Tag: #dataops
DataOps is the set of practices that make data delivery fast and reliable: automation, CI/CD, testing and observability. This guide explains the principles, shows what they mean in practice, and gives you 10 steps to get started.
In short: DataOps is agile and automated practices for producing data. The principles of DevOps are applied to data platforms, so that deliveries are fast, tested and trustworthy.
Many organisations have data teams that deliver more slowly than anyone is happy with, and data deliveries that break without anyone noticing until a manager points at an odd figure in a meeting. DataOps tackles both.
1. Why do we need DataOps?
Data teams need DataOps for two reasons: deliveries are too slow, and errors are discovered too late. Both have the same root cause, namely manual processes and responsibility split between development and operations. DataOps attacks the root with automation, continuous delivery and shared ownership of the whole lifecycle of the data products.
The organisation of data teams creates frustration
Frustrated users and managers who want faster data deliveries than they get from their traditional data warehouse is a common situation. Instead of fast deliveries, new needs end up far back in the backlog, behind issues that are more urgent. And what is urgent is typically daily operations and necessary upgrades, not value-creating development.
Why does it end up this way? The data warehouse team becomes trapped by its own success: it takes on data flows, datasets and reports for an ever-growing number of user groups, everything has to be maintained, and eventually the capacity to build new things is eaten up by maintenance. The business ends up as the customer who is never satisfied, and IT as the supplier that always prioritises something else. That creates friction.
More complex data platforms require new ways of working
Data platforms have changed dramatically over the last decade: from traditional on-premise data warehouses with one database system and an ETL tool, to cloud-based platforms with object storage without a capacity ceiling and engines built for large analytical workloads. The volume and variety of data have grown, and usage has shifted from reporting to a broad set of use cases in AI, machine learning and data delivery to other applications.
Data has become software. Software needs data. So we need to borrow the methods of software development, which has matured faster than the data world traditionally has.
What is DataOps?
The essence can be summed up in three points:
- DataOps changes how we collaborate around data. The methodology is inspired by DevOps and agile principles, and aims to improve the speed, efficiency and quality of data delivery.
- DataOps integrates development and operations instead of splitting responsibility between different teams. That gives faster and more responsive delivery, cross-functional collaboration and learning from mistakes.
- DataOps embraces change through continuous and automated testing, integration and delivery of data.
The principles are set out in the DataOps Manifesto, eighteen principles signed by thousands of practitioners, with “continually satisfy your customer” as the first.
The benefits are concrete: fewer errors, because automation and continuous testing catch problems before users do; higher speed, because data products are delivered faster and decisions can be made earlier; and better collaboration between data people and users, which gives more relevant deliveries. The cost is just as concrete: DataOps is a new way of working that takes getting used to and investment, not a tool you can buy.
2. DevOps vs DataOps
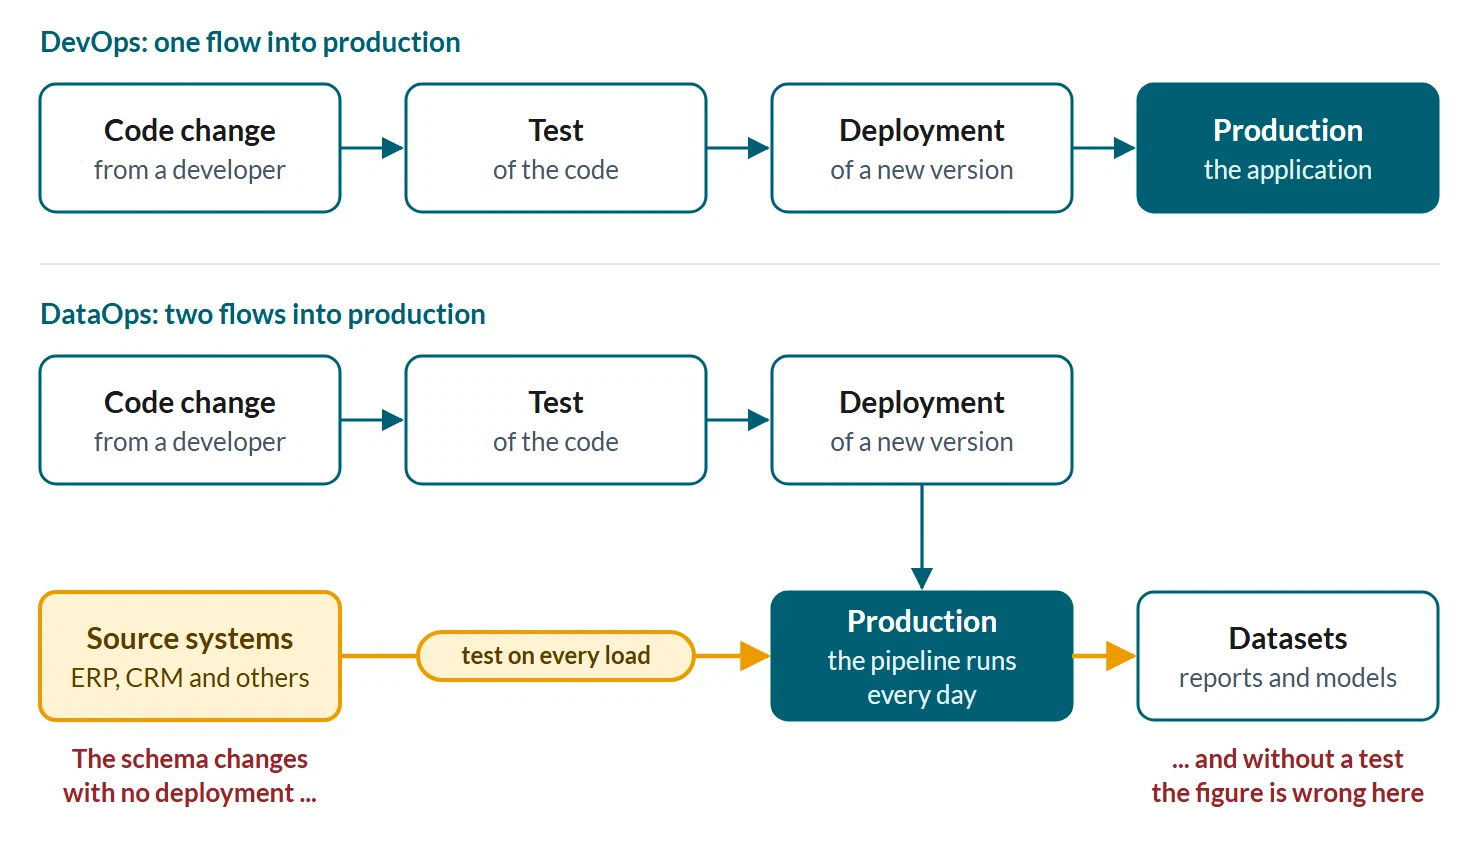
DevOps and DataOps share the same goals and many of the same methods: frequent releases, automated tests and a team that owns both development and operations. The difference lies in what changes. In DevOps, it is the code. In DataOps, it is both the code and the data, and the data changes without anyone on the team deploying anything. That is why DataOps needs everything DevOps has, plus practices for testing, releasing and monitoring the data itself.
DevOps combines development and operations
DevOps is a software development methodology that brings development and operations together to improve quality, efficiency and speed, while making software more reliable and easier to maintain. The thinking shifts from project to product and covers the whole lifecycle. In practice, DevOps means agile development methods and automating everything that can be automated: testing, version control and CI/CD.
A crucial part of DevOps is measuring the development process and making it more efficient by removing obstacles and waste. The DORA research programme (DevOps Research and Assessment) measures software delivery with five metrics. Three are about speed: how long a change takes to get from commit to production, how often the team deploys, and how quickly it recovers from a failed deployment. Two are about stability: the share of deployments that need an immediate fix, and the share that are unplanned and caused by an incident in production. According to DORA, speed and stability go together: the best teams do well on all five.
When the development team is also responsible for operations, it is in the developers’ own interest that the software works well and needs little maintenance. And from agile, DevOps inherits what matters most: clear lines of communication between stakeholders and a continuous feedback loop from end users to developers.
DataOps takes the same responsibility for data products
DataOps came five years after DevOps: the first DevOpsDays conference was held in Ghent in 2009, and Lenny Liebmann, a contributing editor at InformationWeek, first used the term DataOps in a blog post for IBM in June 2014. DataKitchen, which maintains the DataOps Manifesto, points out that a DataOps team must control the data flowing through production as well as the code, and that the data changes independently of the code.
To understand how DataOps differs from DevOps, we need to understand how data development differs from software development. Put simply:
Business applications are about automating and improving business processes. Data development is about deriving insight from the data those processes and applications create.
The most important difference is the complexity that comes with the data itself. Data changes continuously and comes from many sources, which makes data pipelines demanding to develop and maintain. Data development also sits downstream: it is at the mercy of changes in the business applications it pulls data from, without owning them. When a source system changes a schema, the fault is not yours, but it is your dashboard that shows the wrong figure.
Six differences in practice
A DataOps team uses the same tools for version control and CI/CD as a DevOps team, but it has to work differently in six areas:
| DevOps | DataOps | |
|---|---|---|
| When tests run | Before deployment, on the code | Before deployment on the code, and on every load on the data that arrived |
| Test data | Can be created for the test | Must resemble production, or the test says little about what happens there |
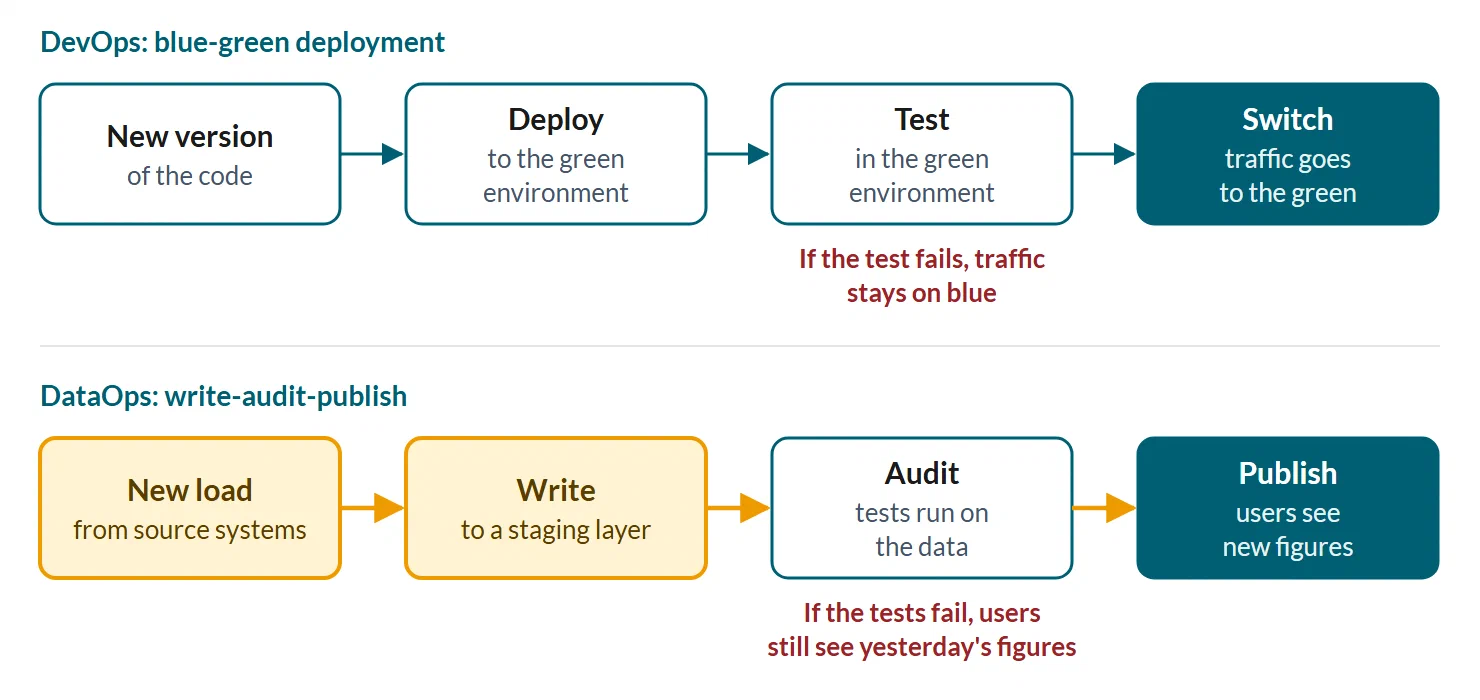
| Release | New code is deployed, and a fault is rolled back | New data also needs a controlled path to users |
| Monitoring | Whether the service responds, how fast and with which errors | Also whether the data is fresh, complete and has the expected schema |
| How faults show up | Usually as an error message or something users cannot do | Often as a figure that looks right but is wrong |
| Measurement | The five DORA metrics | DORA metrics for the code, but no common standard for the data |
A transformation can be written correctly and still give the wrong answer on the data it meets in production. That is why tests must run against data that resembles production, and modern data platforms make this cheap. Snowflake can clone a table so that the clone initially shares storage with the original, and dbt can build only the changed models and use the production version of the rest.
In DevOps it is the code that gets deployed, but in DataOps every new load of data also needs a controlled path to users. The pattern is called write-audit-publish: the data is first written to a staging layer, audited, and published once the tests pass. Write-audit-publish is the data equivalent of blue-green deployment in DevOps, where the new version is tested in a separate environment before traffic is switched over. Apache Iceberg supports the pattern with branches at table level.
Where a data team should start
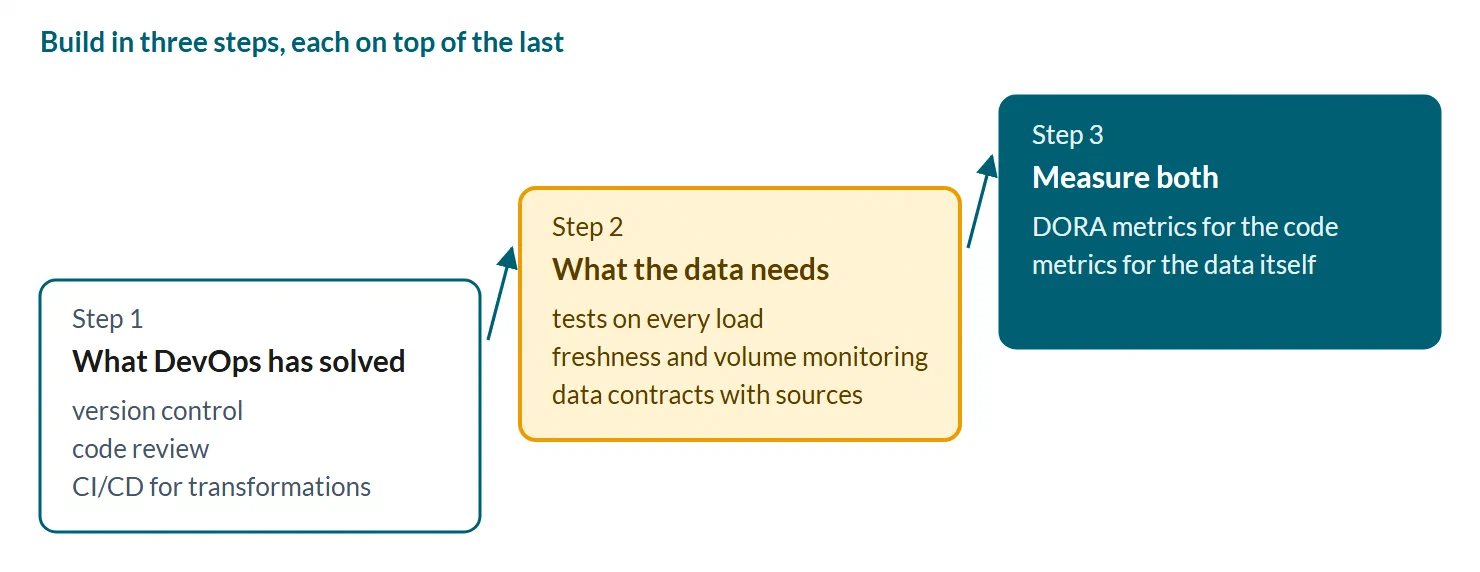
Our advice is to start with what DevOps has solved: version control, code review and CI/CD for all transformation logic. Check that the foundation holds before you build on it. Mirco Hering, who assesses how far organisations have come with DevOps, describes a conversation he has had many times. The team says yes, it does continuous integration, but the CI server builds the code once a week and runs no automated tests. Ask yourselves how often your tests run, and whether a failed test stops the deployment.
Then add what the data needs: tests that run on every load, monitoring of freshness and volume, and data contracts with the sources that change without warning. What the data is for decides how strict the tests need to be, and we have written about that in our article on data quality.
Measure both: DORA metrics show whether you deploy often and safely, but they say nothing about the quality of the data you delivered this morning. For the data, you need metrics of your own, for example how often a table is late and how many data errors users found before the team did. Chapter 5 is about the errors that raise no alarm.
3. Agile development is the foundation for DataOps
Most of DevOps and DataOps is a natural evolution of agile development: develop incrementally in small iterations, deliver often and gather feedback continuously. The four values of the Agile Manifesto are reflected directly in DataOps:
- Individuals and interactions over processes and tools: tools and processes contribute a lot in DataOps, but even the best ones do not help if the product does not deliver what users need. Clear roles and cross-functional teams that can deliver end to end are the foundation.
- Working solutions over documentation: start with a minimum viable data product and expand by business priority. Having operations responsibility in the team means the developer who built the solution also troubleshoots it, and then the documentation naturally becomes good enough, because nobody wants to be constantly firefighting their own code.
- Collaboration over contracts: data owners, data developers, data users and infrastructure work towards a shared result, like a team around a service.
- Responding to change over following a plan: new data sources, changing business requirements and new regulatory requirements are the norm in data development, not the exception. Automation and continuous delivery are what make change cheap.
From Lean and quality management, DataOps takes three more principles: eliminate waste and keep code and platform as simple as possible; optimise the whole process from design to delivery, not individual parts; and base improvement decisions on measurements. The last one is a recurring problem in data teams: monitoring, logging and alerting are rarely good enough for anyone to know where the time and the errors arise.
4. DataOps in practice: the four main areas
In practice, DataOps consists of four areas: automation, continuous delivery, quality management and collaboration. Automation removes manual errors, CI/CD makes changes safe to release continuously, quality management catches errors before users do, and collaboration ensures that deliveries meet a real need.
Automation
Automation is used in many areas to increase efficiency and reduce the risk of errors:
- Data collection and transformation: automated jobs fetch data from the sources, catch errors and transform it into analysis-ready formats.
- Testing and validation: automated tests ensure data quality, from simple schema checks to logical tests across datasets.
- Orchestration: tools such as Airflow coordinate loading, transformation and validation in the right order, driven by dependencies rather than clock times. A classic mistake is running job B at 03:00 because job A “is usually finished” by then; defined dependencies, retry logic and a backfill strategy separate solid orchestration from fragile.
- Monitoring: performance, errors and freshness are tracked automatically, so that problems are detected and fixed quickly.
- Model development and deployment: version control and CI/CD tools manage changes between environments, including for machine learning models.
- Documentation: metadata, change logs and data lineage are generated from the code instead of being maintained by hand.
- Everything as code: the prerequisite for automation is that as much as possible is expressed as code: infrastructure through tools such as Terraform, transformation logic through tools such as dbt, and analysis through notebooks.
Continuous delivery
CI/CD stands for continuous integration and continuous delivery, the practices that let changes go into production continuously and safely:
- Continuous integration (CI): developers merge code changes into the main branch often, and every change is tested automatically, so that errors are found as early as possible.
- Continuous delivery (CD): changes that pass the tests are automatically prepared for deployment to test and production, with code review where needed.
Quality management
Quality management is about making sure the data is accurate, reliable and useful. In modern data teams, testing is often structured according to the test pyramid: most fast, cheap unit tests at the bottom, integration tests in the middle (in dbt projects, these are the tests that run against the database, such as unique and not_null), and a few expensive end-to-end tests at the top. In addition:
- Quality measurements in production: the field is called data observability and has grown into its own component class in data platforms.
- Data quality as code: the expectations of a dataset, such as freshness, complete columns and valid values, are declared in versioned code and enforced close to the source, so that breaches are caught before they spread downstream. This is also the core of a data contract.
- Data catalogues and lineage: metadata, quality information and tracking of where the data comes from make quality understandable throughout the lifecycle.
- Dialogue about business needs: quality is ultimately a question of “good enough for what?”, and that answer is owned by the business, not the data team.
Collaboration
Instead of splitting development and operations responsibility between different teams, DataOps integrates the functions. Two principles recur among those who succeed:
- Data delivery is organised around business value: cross-functional teams, owned and led by the business, deliver what it takes to realise the benefit, including training and process changes, not just technical deliverables.
- A dedicated platform team delivers a good user and developer experience: the platform team treats developers and users as customers, so that data can quickly be used and built upon. We have written more about this model in Data platform as a service.
5. The errors that raise no alarm
The reason quality management and observability deserve so much space in DataOps is that the most dangerous errors in data pipelines do not crash anything. They deliver wrong data silently. Ben Rogojan (Seattle Data Guy) has summarised five types of failure that pass both syntax checks and unit tests:
| Failure type | What happens | The symptom |
|---|---|---|
| Schema drift | The source changes a field name or data type without the pipeline breaking | Downstream models keep running with empty or wrong fields |
| Partial load | API limits or timeouts stop the load halfway | The aggregates look right but are missing a few per cent |
| Stale data | The source stopped updating, the pipeline ran fine | The dashboard shows figures from a day and a half ago |
| Late-arriving dimensions | Fact rows arrive before the dimensions are updated | Joins return empty values without warning |
| Hardcoded assumptions | Business rules are fixed in SQL with no expiry date | The pipeline delivers wrong figures from the day the assumption stopped holding |
The common thread: the pipeline ran, the tests passed, and the data was still wrong.
This is what separates monitoring from observability. Monitoring tells you that something went wrong; observability tells you why, and catches what never reports itself. In practice, observability consists of four layers: lineage (where does the figure come from), data quality metrics over time (null rates, row counts, freshness), performance and cost metrics per run, and the link to business impact. Without the last layer, you know that a table is late, but not whether it matters.
Towards the sources, the answer is data contracts: clear, tested agreements on schema, freshness and content that fail fast and close to the source instead of surprising people downstream. The gain can be measurable. Monzo, the British digital bank, has more than 100 teams contributing to a data warehouse with over 12,000 dbt models, and the bank introduced interfaces: dbt models that a team declares as a contract other teams can build on. About 30 per cent into the migration, Monzo reported roughly 40 per cent lower costs and roughly 25 per cent faster data delivery in some of the domains. The gain comes from the whole rebuild, with fixed model layers and automated standards in CI as well as the interfaces, and the bank itself says it is early days.
6. DataOps in the age of AI
Since this guide was first written, AI-assisted development has gone from experiment to everyday practice in data teams. dbt Labs’ industry survey State of Analytics Engineering 2026, with responses from 363 data practitioners and leaders, puts numbers on the shift: 72 per cent prioritise AI-assisted coding in their development workflows, and the share that has increasing trust in data as a priority has risen from 66 to 83 per cent in a year. At the same time, 71 per cent cite incorrect or hallucinated figures reaching stakeholders as a top concern.
That is the DataOps point in a nutshell: AI scales the production of analytics faster than its verification. When both people and AI agents write transformations, the tests, contracts and observability from chapters 4 and 5 become the very limit on how fast you can safely go. Three consequences are worth taking away:
- Documentation becomes machine-readable infrastructure. Model and column descriptions are a good starting point, but an agent needs more: structured metadata on ownership, valid values and business rules, in a format it can read directly. The better the documentation, the more safely AI tools can generate correct models without hand-holding.
- Conventions must be enforced by machines. Style rules and coding standards that only exist in a document are not followed by an agent that has never read it. Linters and pre-commit checks enforce the conventions regardless of who, or what, wrote the code.
- AI moves into orchestration. Apache Airflow now has an official provider, common.ai, that runs model calls and tool-using agents as tasks in the workflows. Then the DataOps practices become the guard rails: without tests, contracts and observability, you have only automated the production of errors.
Curated, tested and documented data was good practice before. Now it is the prerequisite for using AI on the data. It is the same order that applies to data products: foundation first, then AI.
7. How to get started: 10 steps
DataOps is introduced step by step: understand the principles, get the stakeholders on board, build a cross-functional team, choose a first use case with business value, and scale as the practices settle. The ten steps below are the order we recommend:
- Understand the principles: DataOps is more than tools; it changes how teams collaborate on data. Start by understanding what the methodology involves.
- Establish needs and goals: identify the problems your current approach creates, and define what you want to achieve, such as faster delivery, better data quality or greater flexibility.
- Identify the stakeholders: managers, data engineers, analysts and business users must support the change for it to succeed.
- Build a cross-functional team: bring together people with different skills, from data engineering and analytics to business, infrastructure and security.
- Find the first use case: bring in raw data and make it available for a first use case that delivers business value. Expand the platform’s capabilities as the use cases require.
- Establish architecture principles: a few overarching principles for the target architecture, but choose only the technology the first use case needs.
- Choose tools: cover data collection, transformation, testing, orchestration, monitoring and deployment. Define rules for data and metadata early.
- Introduce the methods: use agile methods for the workflow, and the DataOps practices from chapter 4 to automate delivery and monitor quality.
- Start small and scale gradually: begin with a manageable part of the data landscape and expand as the team gains experience of what works.
- Measure and improve: use metrics for data quality, delivery speed and user satisfaction to drive continuous improvement.
DataOps is an iterative process. The most important thing is to build a culture of collaboration, continuous learning and improvement.
Working in an agile way also takes time, experience and support from the organisation around you. If the stakeholders around the product do not understand or cannot support agile delivery, it will be hard to succeed. It often pays to bring in an agile coach with experience from data development for a few months. And do not break up a team without good reason: it always takes time to get a new team to perform, even when every individual is experienced.
8. Summary and frequently asked questions
DataOps in brief
DataOps is a methodology that improves how organisations collaborate on data. It draws inspiration from DevOps and agile principles, and improves the speed, efficiency and quality of data delivery through automation, continuous testing and delivery, quality management and close collaboration. The most dangerous data errors raise no alarm, which is why observability and data contracts are as central as CI/CD. And in a world where AI generates more and more of the code, it is the DataOps practices that decide whether the speed creates value or just faster errors.
Frequently asked questions about DataOps
- What is DataOps? DataOps, short for data operations, is a methodology that improves the speed, efficiency and quality of data delivery. It draws on principles from DevOps and agile development, and focuses on collaboration, automation and continuous improvement.
- How does DataOps improve data quality? Through automated testing in the development process, data quality declared as code close to the sources, and observability in production that catches the errors that raise no alarm, such as schema drift and stale data.
- What is the main difference between DataOps and DevOps? Both combine development and operations using the same methods. The difference is what changes: in DevOps it is the code, in DataOps it is also the data, and the data changes without the team deploying anything. That is why DataOps also needs tests on every load, test data that resembles production, a controlled path for new data to users and monitoring of the data itself.
- What role does automation play in DataOps? Automation is used in data collection, transformation, testing, orchestration, monitoring, deployment and documentation. The prerequisite is that as much as possible is expressed as code.
- What does CI/CD mean in DataOps? Continuous integration means that code changes are merged and tested automatically several times a day. Continuous delivery means that changes that pass the tests can be deployed safely to production on an ongoing basis.
- Does AI change the need for DataOps? Yes, it increases it. AI-assisted development scales the production of analytics faster than its verification, so tests, data contracts and machine-readable documentation go from good practice to prerequisite.
- How do we get started with DataOps? Understand the principles, put together a cross-functional team, choose a first use case with business value and scale gradually. Chapter 7 has a 10-step list in the order we recommend.
Learn more about DataOps
- The DataOps Manifesto: the eighteen principles behind the methodology, written and signed by practitioners.
- What Is DataOps? (DataKitchen): why a DataOps team must manage both the code and the data, from the company that maintains the manifesto.
- DORA’s guide to the five metrics (DORA): how speed and stability in delivery are measured, as referred to in chapter 2.
- How to build an effective DataOps team (TechTarget): how to organise the team for DataOps.
- State of Analytics Engineering 2026 (dbt Labs): the industry survey behind the figures in chapter 6, on AI adoption and trust in data.
How Glitni can help with DataOps
We have built DataOps practices into data platforms at large Norwegian organisations, and can help with:
- Strategy and planning: analysis of your current data ecosystem, identification of gaps and an action plan covering methodology, process and choice of tools.
- Implementation: automated data pipelines, CI/CD processes and observability, from setup to production.
- Tool selection and integration: selection and integration of tools for transformation, orchestration, monitoring and infrastructure as code, tailored to your needs.
- Training and change management: DataOps often requires a cultural shift. We have long experience of change processes in data, and make sure the team both understands and owns the new way of working.
Are you considering DataOps, or do you have a data platform where delivery is slower than you would like? Send us a message for a chat.