
Contents
Data strategy: what it is, and what it must answer for AI

Category: Data Strategy | Tags: #data strategy, #ai, #data governance
The leadership team asks whether you are ready for AI, while the teams pull in different directions. The data strategy is the document that chooses what gets built first in the layers beneath the AI ambition, and what is left out. This article shows which problem it solves, what it should contain, what form it takes, and how to prioritise when every initiative looks equally important.
In short: A data strategy says how data will be used to reach the business goals, who owns it, what platform is needed and what skills have to be built. The problem the strategy solves is that the data work otherwise becomes random use cases around the organisation, without the attention and money from the leadership team that investing in coherence requires. AI has made the strategy more important. The AI ambition now usually sits at the top of the hierarchy of needs, and the strategy has to give direction to the four layers beneath it.
Data engineers build pipelines for what they think the analysts need. The analysts produce reports nobody asked for. The CIO wants an overview of data quality, and the CDO is not quite sure what is in use. And the leadership team asks whether we are ready for AI.
Each initiative has good intentions. Hard work is wasted when everyone pulls in different directions, and buzzwords leave a bad taste when we have not defined what the words mean for the organisation.
Many have a data strategy that revolves around what is most advanced, and what feels most exciting: AI, language models, prediction, automation. Most organisations still lack bread and water: access to the data, a platform that is stable, and agreement on what a customer is. This article answers which problem a data strategy solves, what happens without one, what it should contain, what form it takes, and how to prioritise when every initiative looks equally important.
What is a data strategy, and do you really need one?
A data strategy is a plan for how the organisation will use data to reach its business goals. The strategy says what data will be used for, who owns and manages the data, what architecture and platform are needed, and what skills the organisation has to build. A data strategy is not a technology strategy. It starts with the business goals and ends in ownership, data quality and delivery.
Now for the objection. Sebastian Hewing of Data Action Mentor reports a debate with a former McKinsey partner, a former head of data strategy at Capgemini and the CDO of a large European marketplace. Everyone agreed that data should serve the business strategy, and that the name of the document matters less. The most controversial claim was this:
We agree with the order, and disagree that the order makes the document redundant. The choices about what you build first, who owns what and what you leave alone have to be written down somewhere. Call the document what you like. A data strategy can be the tool you need to get the leadership team’s attention to invest in coherence, rather than solving random use cases here and there.
Tristan Burns, who has led data and analytics in Pizza Hut’s digital business, takes one step further back. His first data strategy consisted of items like “Deploy this tool by this date. Close all tickets in 24 hours. Create a suite of dashboards.” He assumed there was a business strategy above him to align with, and found a list of ambitions and targets with no choices behind them, the leadership’s version of the checklist he had written himself. The mark of an activity list dressed up as a strategy is that every item is something to be done by a date, not a choice about what gets deprioritised. Find out whether the business strategy is a strategy before you point the data strategy at it.
What happens without a data strategy?
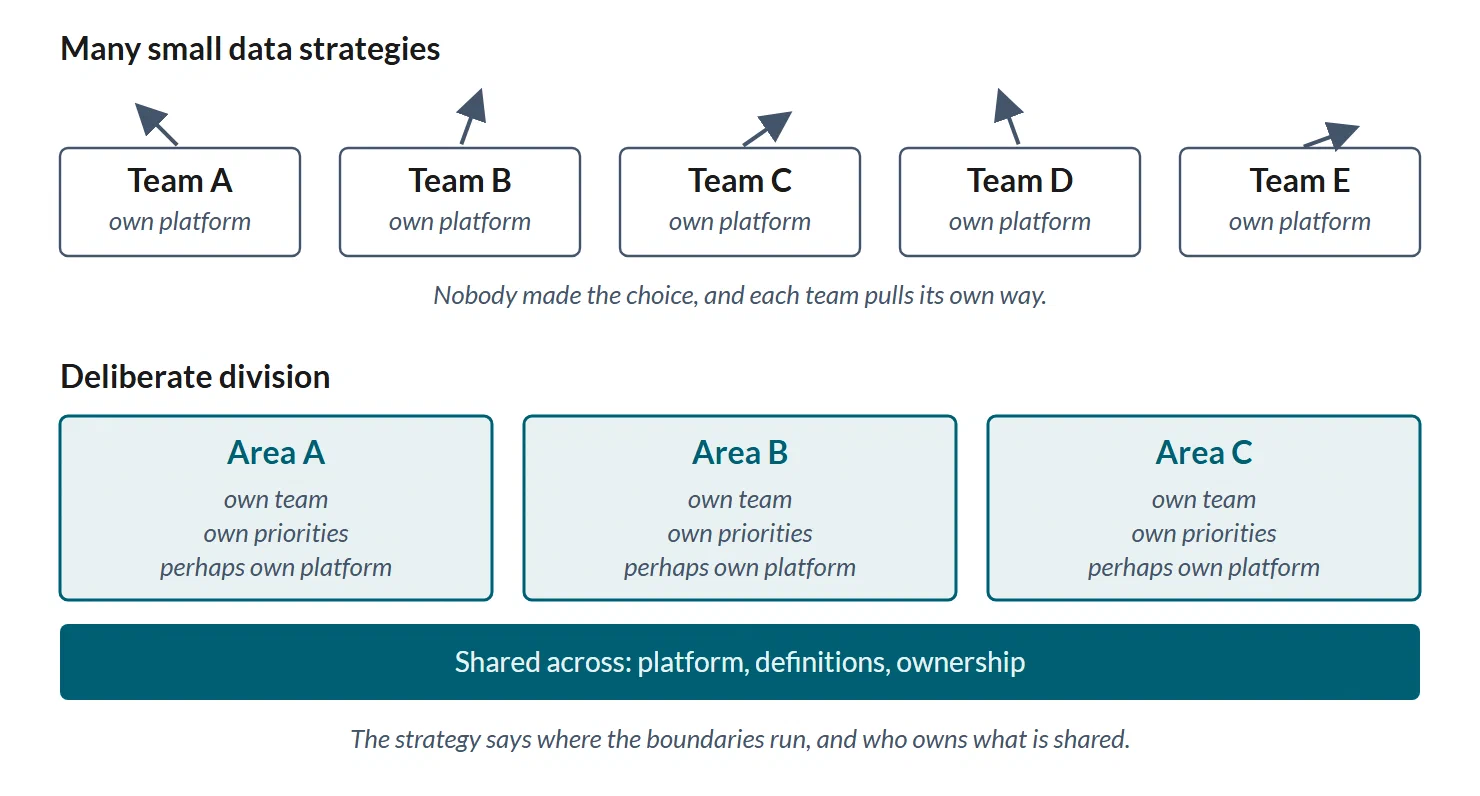
In most cases, the absence of an established data strategy does not mean the organisation lacks one, but that it has many small data strategies. The small strategies live in the data engineer’s task list, in the tool chosen in 2019 and in the way the analytics team sets up its reports. Each has its own logic. Together they give no direction the organisation has taken a position on.
Today most teams have heard that everything is about AI and agents, just as a few years ago they heard that data was the new oil, through data science and big data. Without a shared goal, each team finds its own solution, and the teams pull in different directions. The people who work with data also find it hard to prioritise well: without a strategy there is nothing to measure an initiative against, so the newest wish or the loudest voice wins.
The result is that data ends up in silos, solutions have a short lifespan, and we hire the wrong people because we cannot see what skills are needed. Each team recruits for itself, with overlapping roles and central needs nobody owns. The path to the goal keeps getting longer.
One data strategy does not mean all data work has to hang together. A large organisation can deliberately divide its data work into several smaller areas, with their own teams, their own priorities and perhaps their own platform. The difference is that the division is deliberate: the strategy says where the boundaries run, what is shared across them, and who owns what is shared. Many small data strategies are what you get when nobody has made the choice about where the boundaries run.
The data strategy’s hierarchy of needs: AI sits at the top
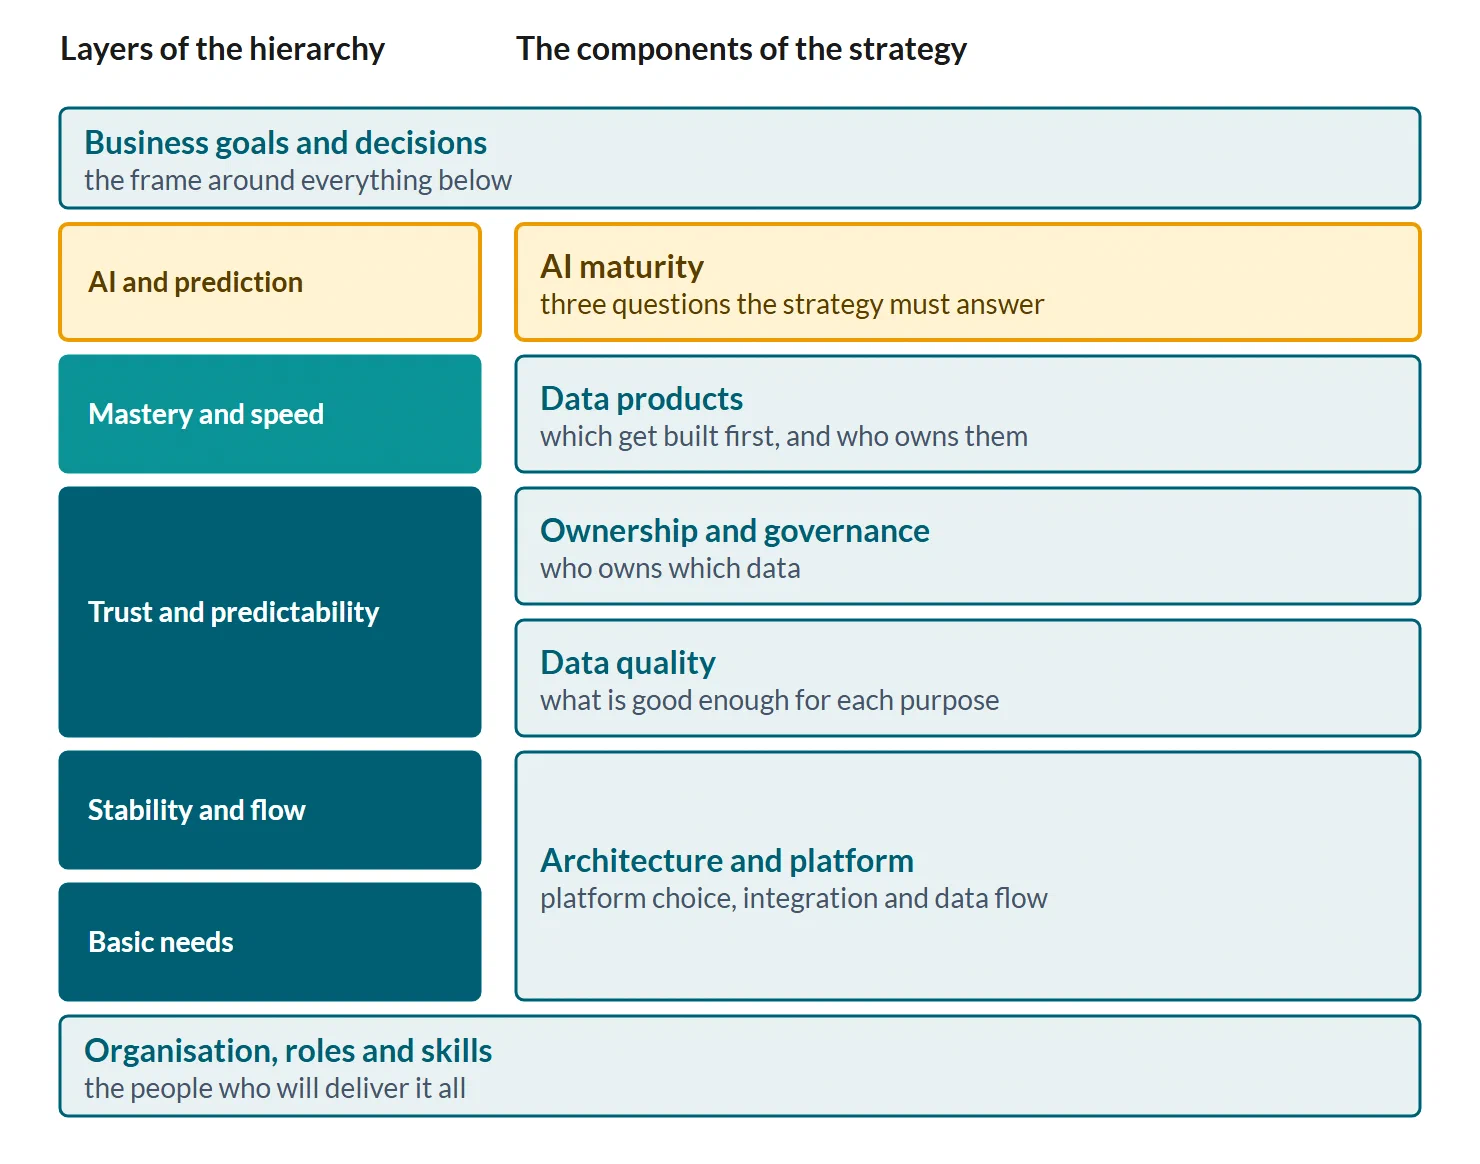
A data strategy can be read as a kind of Maslow pyramid, where the needs build on one another. At the bottom is access to data, then stable operations, then trust in the numbers, then speed and reuse, and at the top AI and prediction. AI does not make the layers beneath redundant, and that is why the strategy has to say what must be in place in each of them.
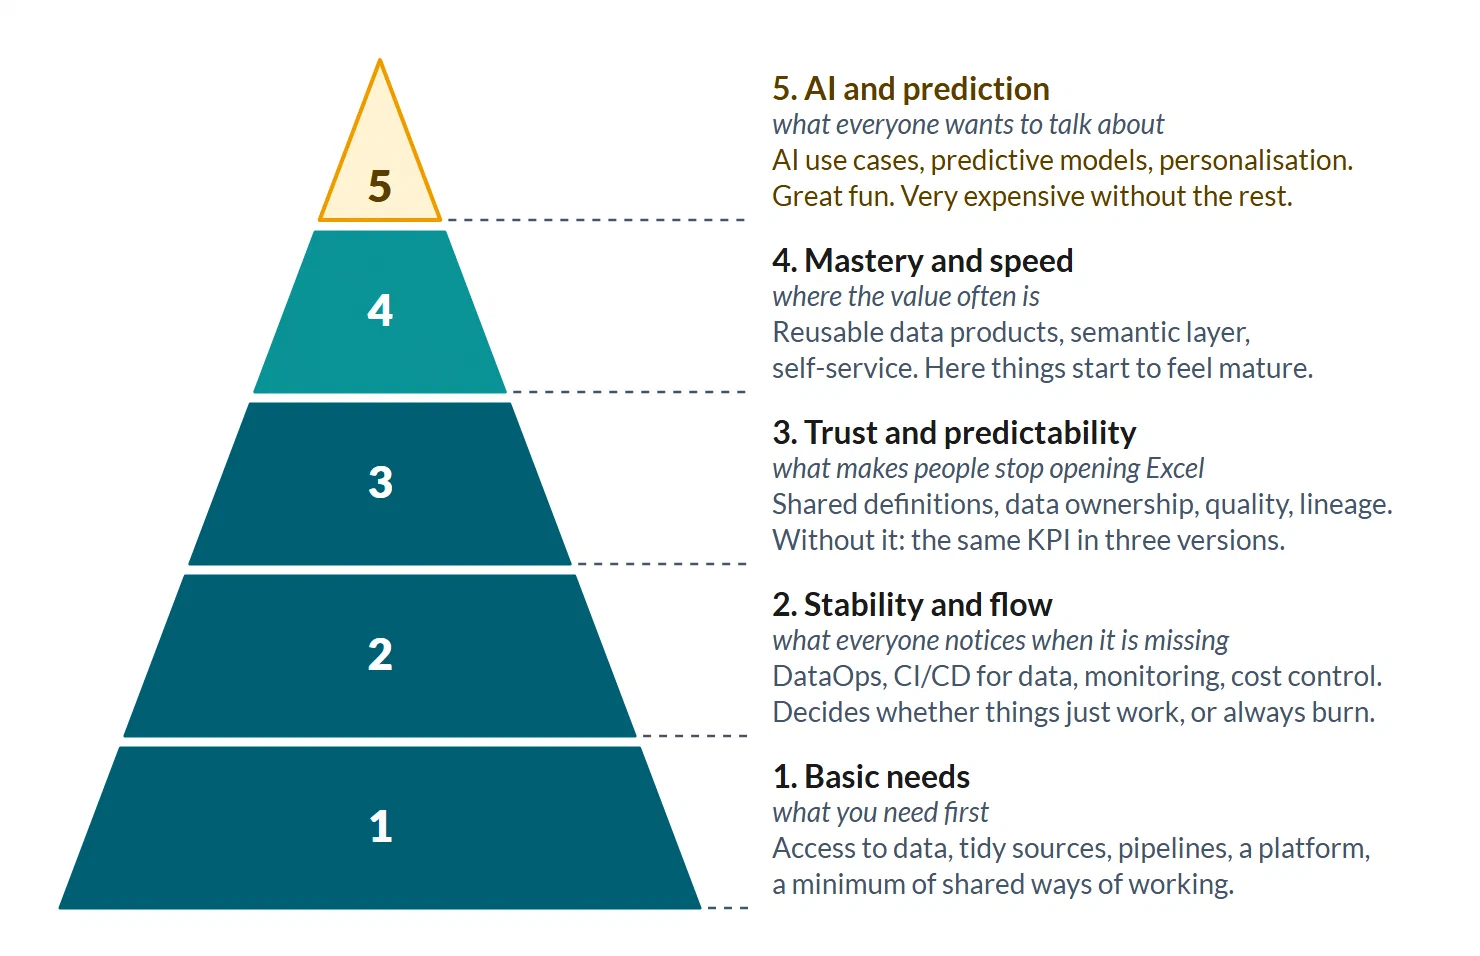
Basic needs are what you need first: access to data, tidy sources, agreements, pipelines out of the source systems, a platform that can store and process, and a minimum of shared ways of working. Without the basic needs, the AI strategy becomes a slide deck and a backlog.
Stability and flow is what everyone notices when it is missing: DataOps practice, CI/CD for data, monitoring, cost control and standards for how data is ingested, transformed and made available. The stability layer decides whether the platform just works, or is always on fire.
Trust and predictability is the layer that makes people stop opening Excel: shared definitions, data ownership, data quality, lineage, access control and clear decisions about what is true. Without this layer, the same KPI exists in three versions, and everyone has their own report. How good the data has to be, and who decides, is the subject of our article on data quality.
Mastery and speed is where the value often lies: reusable data products, a semantic layer with shared metrics, self-service, short lead times and experimentation that does not break production. This is the layer where the data work starts to feel mature.
AI and prediction is the top: AI use cases, predictive models, autonomous decisions, personalisation. Great fun. Very expensive without the layers beneath.
The numbers show where most organisations stand. McKinsey found in June 2026 that only 7 per cent of companies have scaled AI across the organisation, and that more than two thirds of those who succeed best point to data as the biggest obstacle. Gartner predicted in February 2025 that organisations will abandon 60 per cent of AI projects that lack AI-ready data, through 2026.
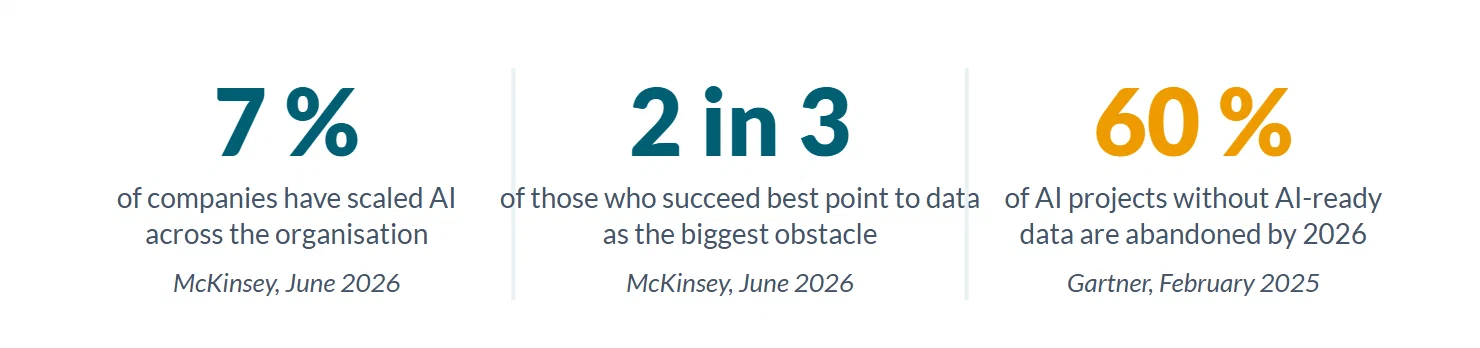
The point is not that you should drop AI, but that AI amplifies the foundation you already have, good or bad. If your definitions and ownership are a mess, AI spreads the mess faster and at larger scale. The infrastructure gets more expensive, and the stakes are higher when the leadership team and the board ask what they got for the money. That is why the data strategy has to give direction to the layers beneath the tip of the pyramid as well.
The strategy connects goals to actions
A data strategy with no link to the business goals is a technology plan. The first question the strategy answers is what the organisation will achieve over the next two to three years, and what role data will play in those goals. The next question is which decisions the data will support. An initiative that cannot name the decision it serves is not mature enough to be prioritised.
The data strategy defines the path from where you are today to where you want to be in the future. Establishing where you currently stand is the first step in any journey. The same goals have different implications for different organisations, simply because they have different people, cultures, technologies and budgets. Some organisations have highly competent data professionals but lack the right processes. Others have a great, modern architecture but low data maturity across the organisation. The differences lead to different paths, even when the goals are the same.
In practice you measure the distance between ambition and current state. The ambition may be personalised customer journeys in real time. The current state may be that customer data lives in five systems, with no shared definition of who a customer is. Where data creates value is the subject of Five places data creates value, and how to get there, of How to create value from data.
Prioritising means choosing what not to do
A data strategy is largely about setting priorities. Some organisations use the word “priority” loosely, and use it about everything they think is important. But prioritising is not about putting stickers on everything you want, and if you focus on everything you are really not focusing at all. Prioritising means making decisions about how to spend time and resources to reach our goals. Prioritising also involves making decisions about what you will not spend time on.
We are often reluctant to use negative words, and to say that we will not prioritise something, or that we cannot do something. We want to focus on the valuable things we will spend time on. Unfortunately, that reluctance tends to backfire. When old assumptions about priorities are not addressed, people will think (or at least hope) that the old priorities still apply. Making it completely clear what we will not spend time on is an excellent way to make it clear what we actually will spend time on, and the clarity helps us avoid discussions and re-negotiations at a later point.
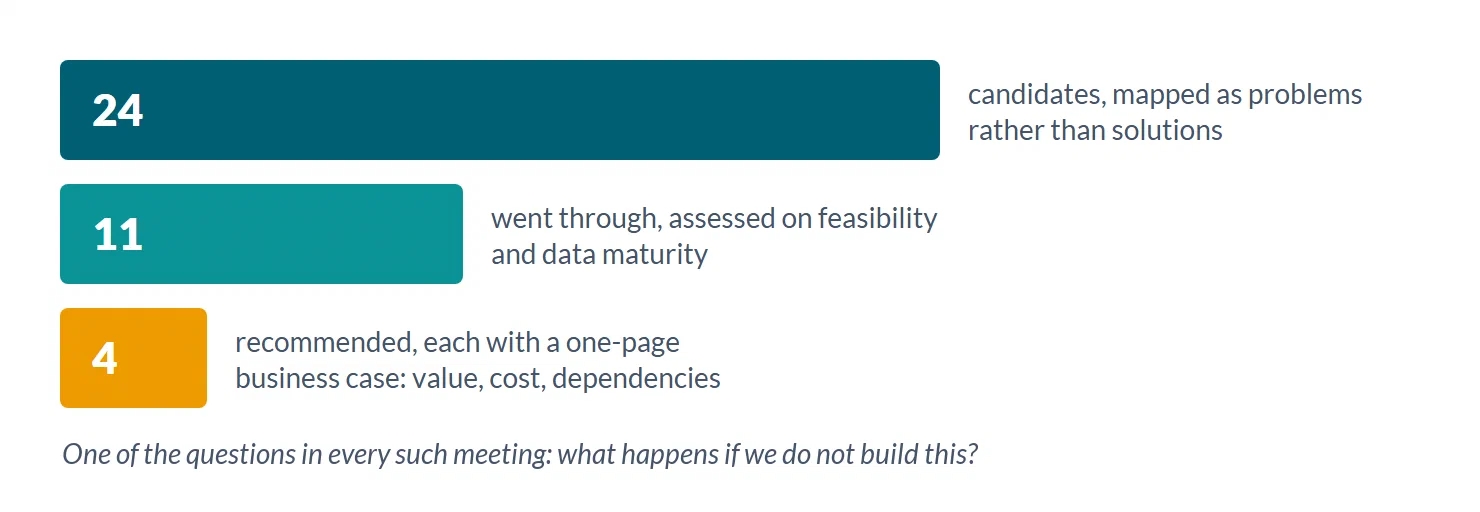
Prioritising now has a method. Nick Zervoudis describes a round at a large consumer goods company after the CFO asked what they were going to do about AI. The team mapped 24 candidates as problems, not as solutions, and assessed them on feasibility and data maturity. 11 went through. 4 were recommended, each with a one-page business case: value over five years, cost, what blocks it and what it depends on. Most of the seven that fell away were profitable too, just weaker alternatives once dependencies and time were counted. One of the questions he wants people to ask in every such meeting: what happens if we do not build this?
A useful distinction runs between three types of action, and a good data strategy has all three.
| Type of action | What it is | Example |
|---|---|---|
| Creates value now | The use cases | A model that suggests the next product |
| Opens for value later | Platform and foundation | Pipelines out of the source systems |
| Reduces risk | Governance, quality, compliance | Data ownership and the documentation the EU AI Act requires |
We have seen organisations spend large sums on advanced analytics projects, only to discover that basic master data for customers and products diverged between the source systems. The project did not stop because the idea was bad, but because the prerequisites were not in place.
What should the data strategy contain?
There is no single answer, but seven components recur in the data strategies that work. They follow the layers of the pyramid: the business goals as the frame, architecture and platform in the two bottom layers, ownership and data quality in the trust layer, data products in the speed layer, AI maturity at the top, and the organisation that will deliver all the components. Map where you stand along each of the seven, and put the effort where the gap between ambition and current state is widest.
1. Business goals and decisions. The strategy starts with what the organisation will achieve, not with what data you have. Sebastian Hewing used to open data projects with three questions he now skips: which BI tool should we use, should we build real time, and what should the architecture look like. The result was a dashboard factory and lost trust with senior management. He now starts with where the company stands, where it is going in twelve months, and who makes the decisions.
2. Architecture and platform (layers 1 and 2). What technical architecture will the strategy be built on: platform choice, integration model and data flow between systems? The architecture follows from the use cases, not the other way round. What a data platform is and should contain, and when distributed ownership fits, is covered in the guides under Read on.
3. Ownership and governance (layer 3). Who owns which data, and who is responsible for it being correct, available and used within the rules? Without clear owners, gaps in accountability open up that neither IT nor the business side takes. When Gartner surveyed 248 data leaders in the autumn of 2024, 63 per cent said they did not have, or did not know whether they had, the governance practices AI requires. The EU AI Act requires data governance and documentation for high-risk systems, and Norway’s new data act sets requirements for metadata about the data that is shared. Neither can be met unless someone owns the data. Read more in our article on data ownership.
4. Data quality (layer 3). Thomas Redman estimates in MIT Sloan Management Review that bad data costs most companies 15 to 25 per cent of revenue, in corrections, double-checking and the errors that follow. It is an estimate, not a measurement, and it sounds dramatic, but we see the effects almost daily. The strategy should say what is good enough quality for each purpose, who keeps the quality up, and how it is measured.
5. Data products (layer 4). How will data be delivered to the people who need it? A data product is more than a dataset in a database: a deliverable with an owner, documented quality and a known format, made so that a specific consumer can use the data without asking. The strategy should say which data products get built first, and who owns them.
6. AI maturity (layer 5). Here the strategy has to answer three questions.
- Which AI use cases come first, and what is good enough for each of them? “Good enough” is defined per use case, because a model that suggests the next product tolerates more noise than one that approves a loan.
- Which data, definitions and owners have to be in place before the first use case goes into production?
- How will an AI agent find out what the data means, without asking? Travis Thompson uses an example in Modern Data 101: an analyst who meets a column called
flag_Acan ask what it means. An agent cannot. The agent assumes, and acts.
Metadata, governance, semantics and access, the things agents need, are largely the platform and governance you are building. Darpan Vyas writes in Modern Data 101 that most of the infrastructure needed to control agents already exists in the data platform, built for governance, lineage, access control and observability. Maturity for agents therefore belongs in the components above. How metadata and ontology make data readable for a machine is the subject of a separate article.
7. Organisation, roles and skills. Data ambitions without the people and structures to carry them out remain plans. The strategy should describe which roles are needed (data engineers, analysts, data stewards, product owners for data and so on), how many full-time equivalents each role requires, how the roles are organised, and which skills have to be built or bought in. An estimate of full-time equivalents per role makes the strategy possible to budget, and shows the leadership team what the ambition costs in people.
The strategy does not need to cover all seven components in equal depth. It should cover the most important ones, and say which get less room for now.
What form does the data strategy take, and when is it delivered?
A data strategy is a short document and a roadmap, not a report. The document has four parts: the vision for the role data will play in the business strategy, the current state along the seven components, the prioritised initiatives with owner, cost and date, and the list of what you will not spend time on. The roadmap says which changes have to be in place by when, and which actions you start with in the first months. The maturity assessments, the architecture assessments and the use cases that were considered and set aside go in the appendix.
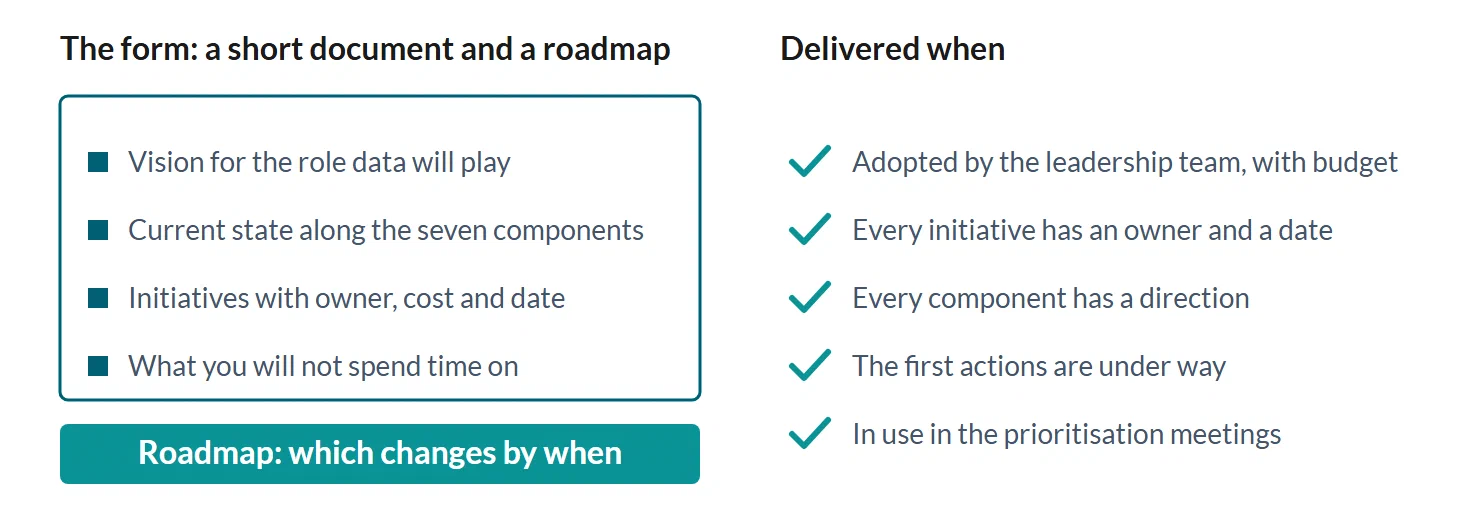
The data strategy is delivered when five things are in place:
- The leadership team has adopted it, and the initiatives have been given budget.
- Every initiative has an owner and a date, and the list of what you will not do is in the document.
- Each of the seven components has a direction, including the ones you leave for later.
- The first actions are under way, not just adopted.
- The strategy is used in the prioritisation meetings, and the employees know it exists.
A document that is written, but neither adopted, budgeted nor in use, is a slide deck.
The data strategy has to be made known
A data strategy has two audiences: the people who will build, and the people who will lead. For the teams it gives direction, meaning what we build, and why. For the leadership team it gives context: what we invest in, what they can expect, and what it depends on. Many data strategies run aground when they are to be anchored and decided.
The data strategy must be known by employees, including those who will not be involved in the implementation. Making the strategy known requires us to show ownership of it and talk about it, much more and to a wider audience than we think is necessary. The goal of the communication is not necessarily to convince or to gather support, but to avoid misunderstandings and the development of many small strategies.
A data strategy that lives in a slide deck but not in the prioritisation meetings is a sign that the anchoring is missing. Colin Hardie writes in Context & Chaos that a data team without a seat when strategy is discussed is an order-taker, however skilled its people are. If you already have a data strategy, you should make sure it is strong and stands firm. An unsteady data strategy has the same consequences as the lack of a data strategy.
Three questions before you write
Before you start on the document, you should be able to answer three questions.
- Is there a business strategy with choices behind it, or a list of ambitions and dates? If the business strategy looks like Burns’s checklist, with tools and deadlines and nothing deprioritised, the work starts there.
- Which decisions will the data support over the next twelve months, and who makes those decisions?
- What will you stop doing once the strategy is adopted?
If you can answer all three, you have most of a data strategy. The rest is writing the strategy down, giving each layer of the pyramid a direction, and talking about it more often than you think is needed.
At Glitni we help organisations with data strategy, from mapping where you stand along the seven components to a roadmap that says what to do first. Get in touch with us if you would like to talk about where to start.
Frequently asked questions about data strategy
What is a data strategy? A data strategy is a plan for how the organisation will use data to reach its business goals. It says what data will be used for, who owns and manages it, what architecture is needed, and what skills have to be built. It is not a technology strategy, and it says as much about what you will not do as about what you will.
What is the difference between a data strategy and an AI strategy? The AI strategy says what you want to achieve with AI, and which use cases come first. The data strategy says what the layers beneath must be able to do for the AI strategy to succeed, meaning access to data, stable operations, trust in the numbers and reusable data products. An AI strategy without a data strategy becomes a slide deck and a backlog of unanswered questions.
Does every organisation need a data strategy? No. A small organisation with one or two people using data needs no separate data strategy, only a business strategy that uses data. Organisations with their own data teams, several systems and ambitions for AI need the choices written down somewhere, whatever the document is called. Without such a document, you get many small data strategies instead of one.
What happens if we do not have a data strategy? You get many small data strategies instead of one. Each team picks its tools and builds for itself, the people who work with data have no basis for prioritising well, data ends up in silos, solutions have a short lifespan, and you hire the wrong people because nobody sees what skills are needed. The data work also fails to get the attention and money from the leadership team that investing in coherence requires, and the AI ambition is left without a foundation.
Who should own the data strategy? Whoever has the authority to prioritise across business areas, often a CDO or an equivalent role. In organisations without a CDO it is usually the CIO, but with the business side close at hand. A data strategy owned by IT alone, without backing from the people who own the data, rarely delivers what it promises.
How long should a data strategy be? Shorter than most people think. The best we have seen are ten to twenty pages with clear priorities and actions that have an owner and a date, plus a roadmap. An 80-page document really tells you that the prioritising has not been done.
How often should the data strategy be revised? We recommend a review at least once a year, and always when something big happens, such as a reorganisation, an acquisition or a merger, new business priorities or new technology choices. At each review you check whether data, people, processes and tools are still set up for the business goals.
Read on
- A complete guide to data products, on how data is delivered as products with an owner and known quality.
- What is a data platform?, on the two bottom layers of the pyramid.
- A guide to data mesh, on distributed ownership in large organisations.
- Data ownership: who owns the data, and what does ambiguity cost?, on component 3.
- Data strategy as a service at Glitni, on how we work with mapping, strategy and roadmaps.
Sources
- Magne Bakkeli: I like to see a data strategy as a kind of Maslow pyramid, LinkedIn, 2 February 2026, in Norwegian. The figure is drawn after the post.
- McKinsey Technology: AI data readiness: the key to scaling impact, June 2026.
- Gartner: Lack of AI-ready data puts AI projects at risk, press release, 26 February 2025.
- Sebastian Hewing: Do we really need a data strategy?, Data Action Mentor, and the post on the three questions he stopped starting with, LinkedIn, June 2026.
- Tristan Burns: I’ve made a huge mistake, Strategies for Effective Data Leadership, 20 August 2026.
- Nick Zervoudis: Value driven prioritisation, The Data Ecosystem, issue 66, 16 August 2026.
- Travis Thompson: New Data Roles to Prep for in an AI-Transitioned World, Modern Data 101, 20 May 2026.
- Darpan Vyas: How to Control AI Agents With the Data Platform You Already Have, Modern Data 101, 17 August 2026.
- Colin Hardie: Four Architectures That Make AI Work, Context & Chaos, 24 September 2026.
- Thomas C. Redman: Seizing Opportunity in Data Quality, MIT Sloan Management Review, 27 November 2017.
This article was first published in 2022 by Carina Eikaas, and was revised and expanded by Magne Bakkeli in 2026.